Verification
The merge gate is local. Grok Bot runs it on the machine that has the
Release tree and checkpoints (AGENTS.md, .cursor/skills/verify-local/SKILL.md).
GitHub Actions compiles, lints, and runs ctest. It does not run PyTorch ULP,
convert round-trip, or verify_diffusion.py on pull requests. Dispatch
.github/workflows/parity.yml only when you want a runner copy of those
commands.
Release gates
Gate |
Proves |
|---|---|
Kernel/unit tests |
C++ kernels match independent references |
PyTorch parity |
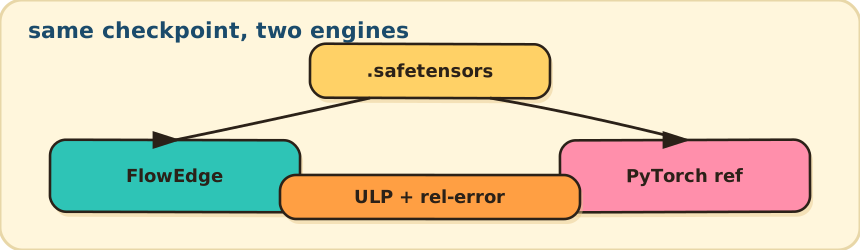
Same checkpoint/input stays within ULP and relative-error limits |
Relay process test |
Real client, shared memory, daemon, deadline result, shutdown |
Generic process test |
Real child service, typed success/rejection, backpressure, shutdown |
Worker-pool tests |
Parallel lanes, freshness, QoS, rolling drain, quarantine, recovery |
Action-delivery tests |
Chunk shape, replacement, timing, freshness, bounds, delta limits |
Mamba adapter tests |
Exact migrated output and real-model generic routing |
Job observability tests |
Fixed event capacity, kinds, progress, migration, timings, exporters |
Trace round-trip |
Canonical bytes for action and generic job records |
Install consumer |
Installed |
Run everything
Linux / Git Bash (Grok Bot local execution):
./scripts/verify_all.sh models/mamba_flow.safetensors
Windows PowerShell against build-win-clang:
powershell -File scripts/verify_local.ps1 -BuildDir build-win-clang
The script builds Core, Relay, tests, benchmarks, every C++ example, generic-job JSONL inspection,
the Relay lifecycle demo, action replay, all metric formats, installation, and a downstream consumer.
Python checks run when their dependencies are available. Transformer HF parity runs when
models/tiny-gpt2 and the converted checkpoint are present.
GitHub Actions also runs .github/workflows/bench.yml for short CPU kernel JSON
(and GPU only when nvidia-smi works). That summary is not policy evidence.
Focused commands
Need |
Command |
|---|---|
C++ tests |
|
Transformer kernels |
|
Transformer HF parity |
|
Transformer latency |
|
PyTorch parity |
|
External-head + streaming smoke |
|
Diffusion python |
|
CUDA DP mix |
|
Policy vs LeRobot |
|
Period rollout |
|
Relay lifecycle |
|
Formatting/static analysis |
|
Benchmarks |
|
Relay benchmarks |
|
QoS overload |
|
Key invariants
Invariant |
Coverage |
|---|---|
Older generations cannot publish as current |
Scheduler, head-pool, job-pool cancellation tests |
Full result rings cannot lose work |
|
Admission includes active and queued lanes |
Multi-lane EDF tests |
Migration is exact and corruption-safe |
Cooperative capsule and Mamba cross-engine tests |
Draining cannot strand accepted work |
Worker drain handoff and queued-work tests |
Lower service classes cannot consume reserved slots |
QoS reservation and equal-deadline tests |
A failed lane cannot silently rejoin |
Quarantine and explicit-recovery tests |
Trace bytes are portable |
Representative little-endian byte assertions |
Event overflow is bounded |
|
Job metrics keep fixed kinds |
|
Hot paths allocate nothing |
Relay and cooperative-job benchmarks |
Queue depth does not multiply clock reads |
Deadline queue benchmark |
Live handoff remains bounded |
Worker drain benchmark |
Controller publication stays bounded |
Action delivery benchmark and multi-rate example |
Public API works after install |
|
Install consumer
cmake --install build --prefix build/install-check
cmake -S test/install_consumer -B build/install-consumer \
  -DCMAKE_PREFIX_PATH="$PWD/build/install-check"
cmake --build build/install-consumer -j
./build/install-consumer/flowedge_install_consumer
New kernels, protocols, adapters, event types, and exporters require a focused test plus inclusion in
verify_all.sh when they add a runnable surface.
CUDA kernel loop
One hypothesis per rebuild. Keep the patch only when the targeted
flowedge_cuda_dp_mix isolate row and native 10-step DDIM p50 both move.
If isolate moves and native does not, revert (#178). Then run matched CUDA
policy replay vs PyTorch; max abs must stay within the existing 1e-3 gate.
./build-cuda/flowedge_cuda_dp_mix models/diffusion_pusht.flowedge.safetensors
# patch the hottest remaining census/mix row in src/core/kernels/cuda/kernels_cuda.cu
./build-cuda/flowedge_cuda_dp_mix models/diffusion_pusht.flowedge.safetensors
python -m flowedge_dev bench policy models/diffusion_pusht.flowedge.safetensors \
  --source models/diffusion_pusht --device cuda --build-dir /path/to/cuda-build \
  --observations bench/artifacts/policy/diffusion-pusht-cpu-replay.observations.npz
Do not retry L=16 conv split-K without a new launch shape; it lost twice.
Do not replace the README threads=1 851 vs 1409 ms CPU figure from a CUDA mix.
Do not replace the published GTX 1650 131 vs 345 ms CUDA replay from a mix
or a new GPU. Residual fusion and BF16/FP16 weight traffic use the same gate:
isolate and native 10-step DDIM (or matched policy p50) on a card that can
cudaMalloc the U-Net. A 4 GB GTX 1650 WDDM/WSL host is not that card.