Capabilities
Core is the in-process engine: convert a policy, pin RSS, sample an action. Relay is an optional sidecar for deadline-aware IPC. Neither replaces LeRobot training, cameras, or e-stop.
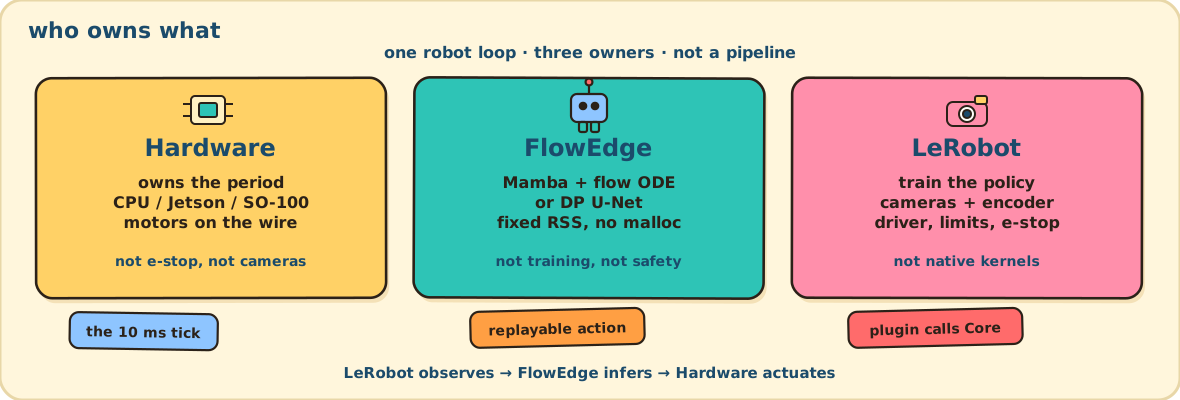
Use Core when the policy and the controller share a process. Use Relay when a sensor or VLA process must hand a condition across a ring and still meet a deadline. The default Diffusion Policy replay loads flowedge.Engine in-process and does not start Relay.
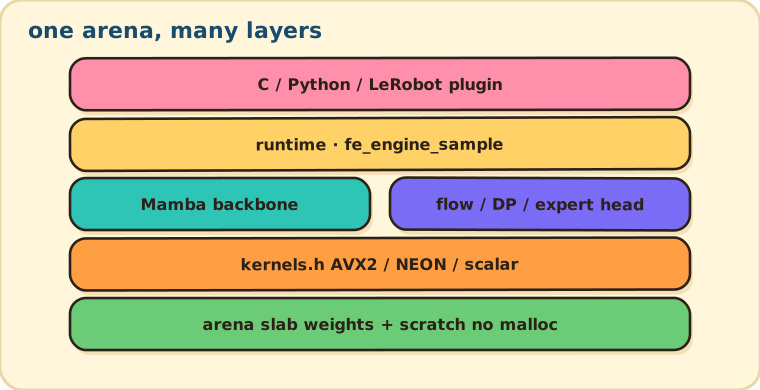
Choose a path
Goal |
Start here |
|---|---|
Flow matching |
|
LeRobot Diffusion Policy, period, |
|
Keep an existing encoder |
|
Streaming Mamba |
|
Snapshot / restore |
|
Cross-process actions |
|
Faster control loop |
|
vs PyTorch |
|
Available now
Area |
Capabilities |
|---|---|
Backends |
CPU scalar / AVX2 / NEON. |
Backbones |
Mamba. Transformer CPU decoder fixture (not a policy) |
Heads |
flow matching (Euler / Heun / RK4); Diffusion Policy (DDIM / DDPM); SmolVLA expert soon |
Models |
|
Precisions |
FP32 / BF16. INT8 no |
Weights |
|
State |
Versioned snapshots; exact restore |
Relay |
Shared memory; EDF; 1–8 workers; action delivery |
Jobs |
Iterative, streaming, speculative; drain / quarantine |
APIs |
C, C++, Python |
LeRobot |
|
Evaluation |
Matched CPU and CUDA replay; period misses; PushT runner |
Contracts
Contract |
Expectation |
|---|---|
Allocation |
Nothing after setup on supported hot paths |
CUDA attach |
Device-resident upload is best-effort; CPU kernels remain unless |
Mutable state |
One engine per concurrent lane |
Action delivery |
Binding, overlap, bounds, per-step delta |
Deadlines |
Predictive admission, not an OS hard guarantee |
Transport |
Shared-memory rings are SPSC |
Not yet
π0 / DiT · native VLM · ROS 2. The Transformer decoder fixture is not a robotics policy. FlowEdge is not a graph runtime, trainer, or safety controller.